Sprint Demo · June 29 – July 10, 2026
TechOps
Observability · Usage & quotas
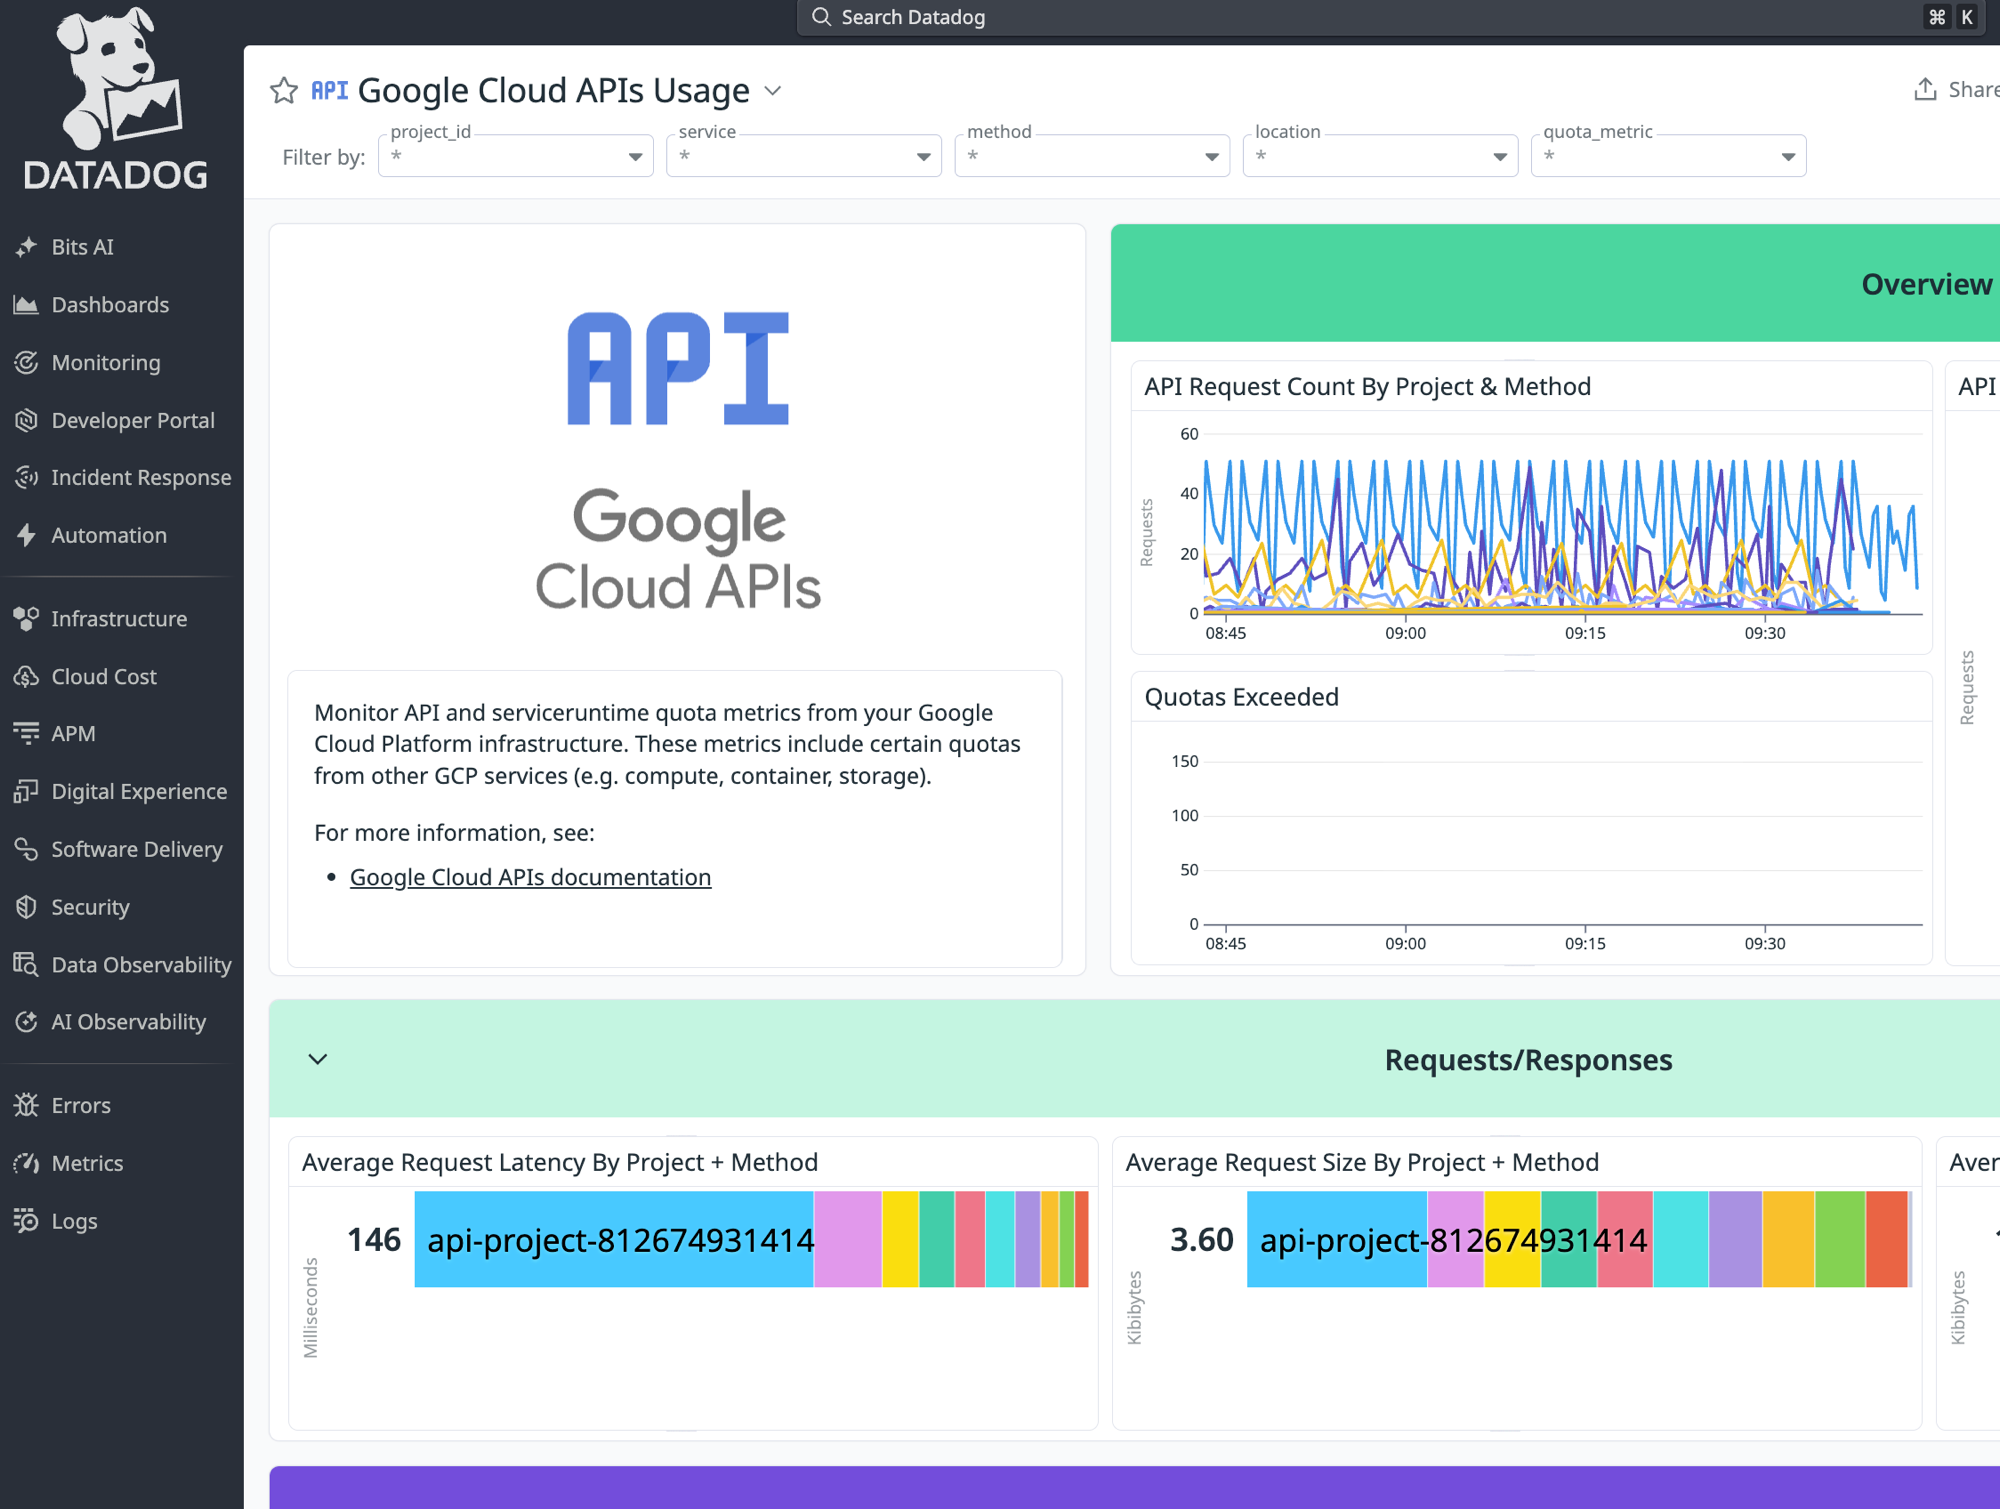
See the limit coming — Google API and Datadog usage monitoring
- The problem: we hit our Google Places API limit and station-page maps on the web started throwing errors
- Now: Google Cloud telemetry flows into Datadog — request counts, latency, and quota usage per API — with alerts before we hit the ceiling
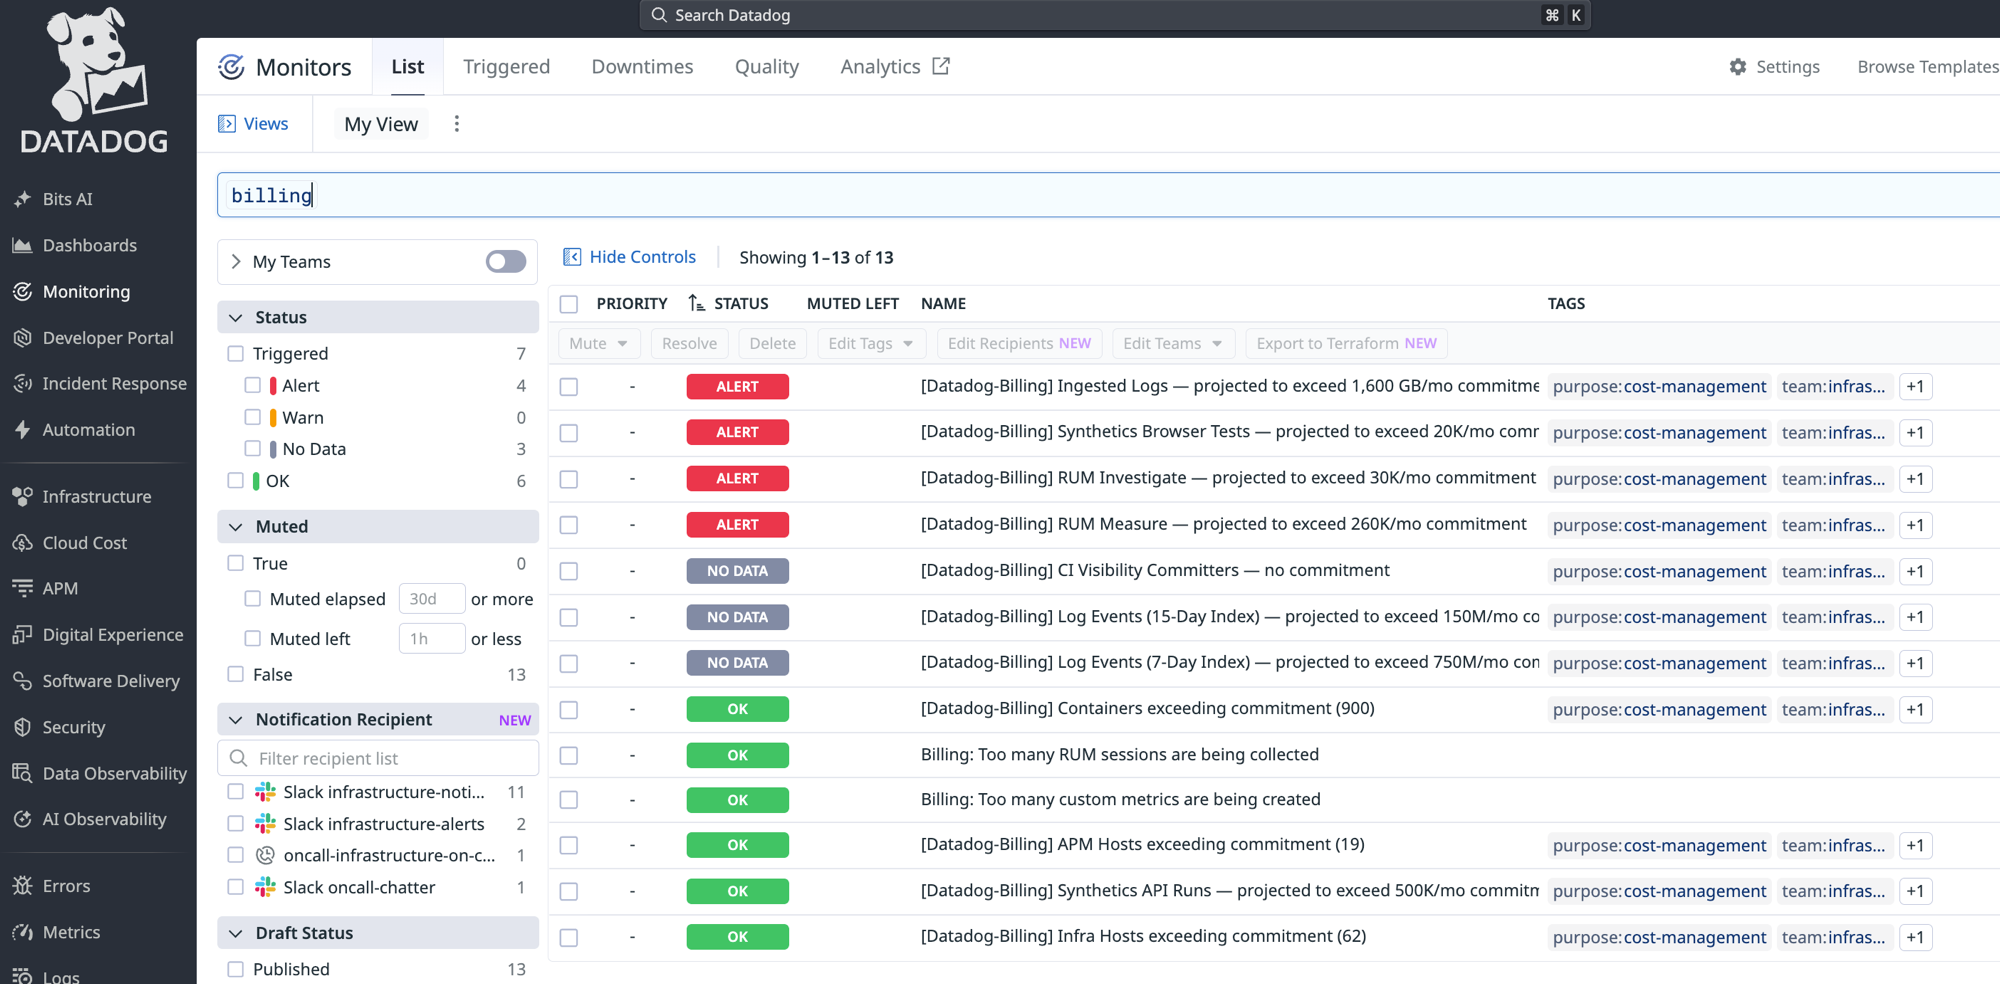
- Datadog billing monitors realigned to our renegotiated contract — every billable usage type has a projected-overage monitor
Infrastructure · Legacy retirement
Retiring the long tail of the legacy WKE cluster
The old ops-nva cluster only goes away when nothing depends on it. This sprint we cut three of the biggest remaining dependencies.
- ~131 Jenkins and Rundeck jobs moved off the legacy dockerhub registry onto ECR — and 12 obsolete jobs retired outright
- Verdaccio shut down — our self-hosted npm registry is gone; packages now resolve from npmjs
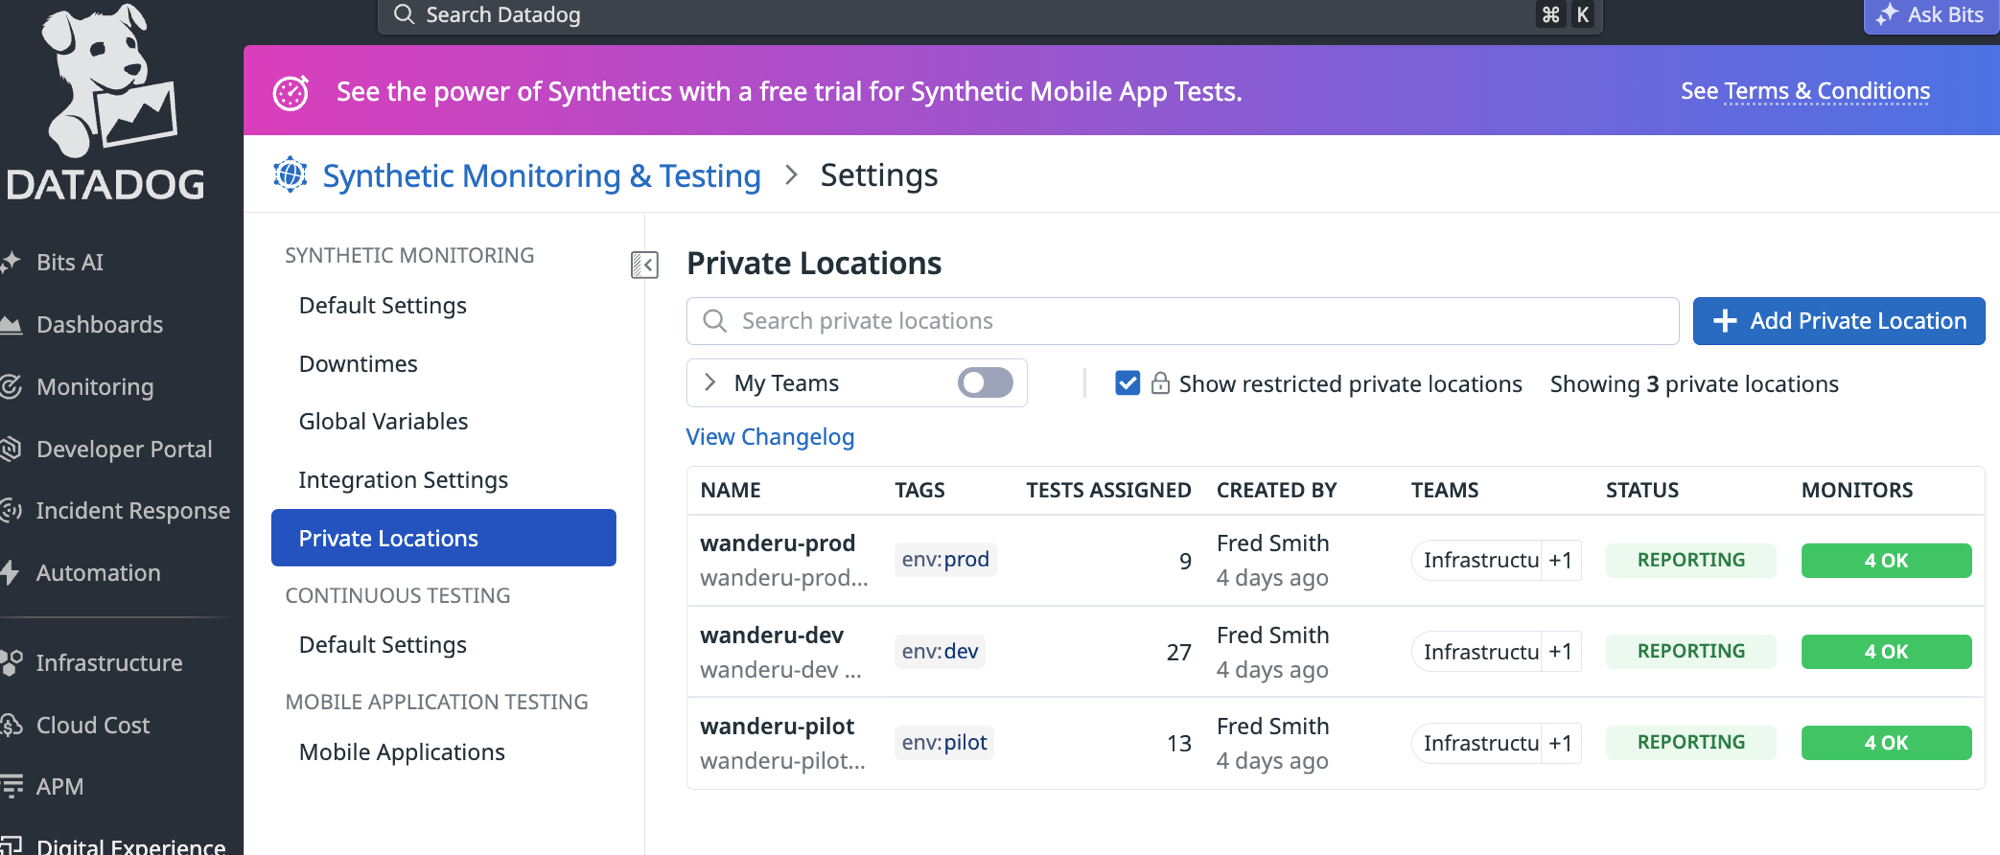
- Datadog synthetics private locations migrated off WKE onto our EKS environments — one per env (dev / pilot / prod), all green
Almost done
Only dockerhub and Burrow remain on ops-nva — and both are ready to retire.
Observability · Kafka
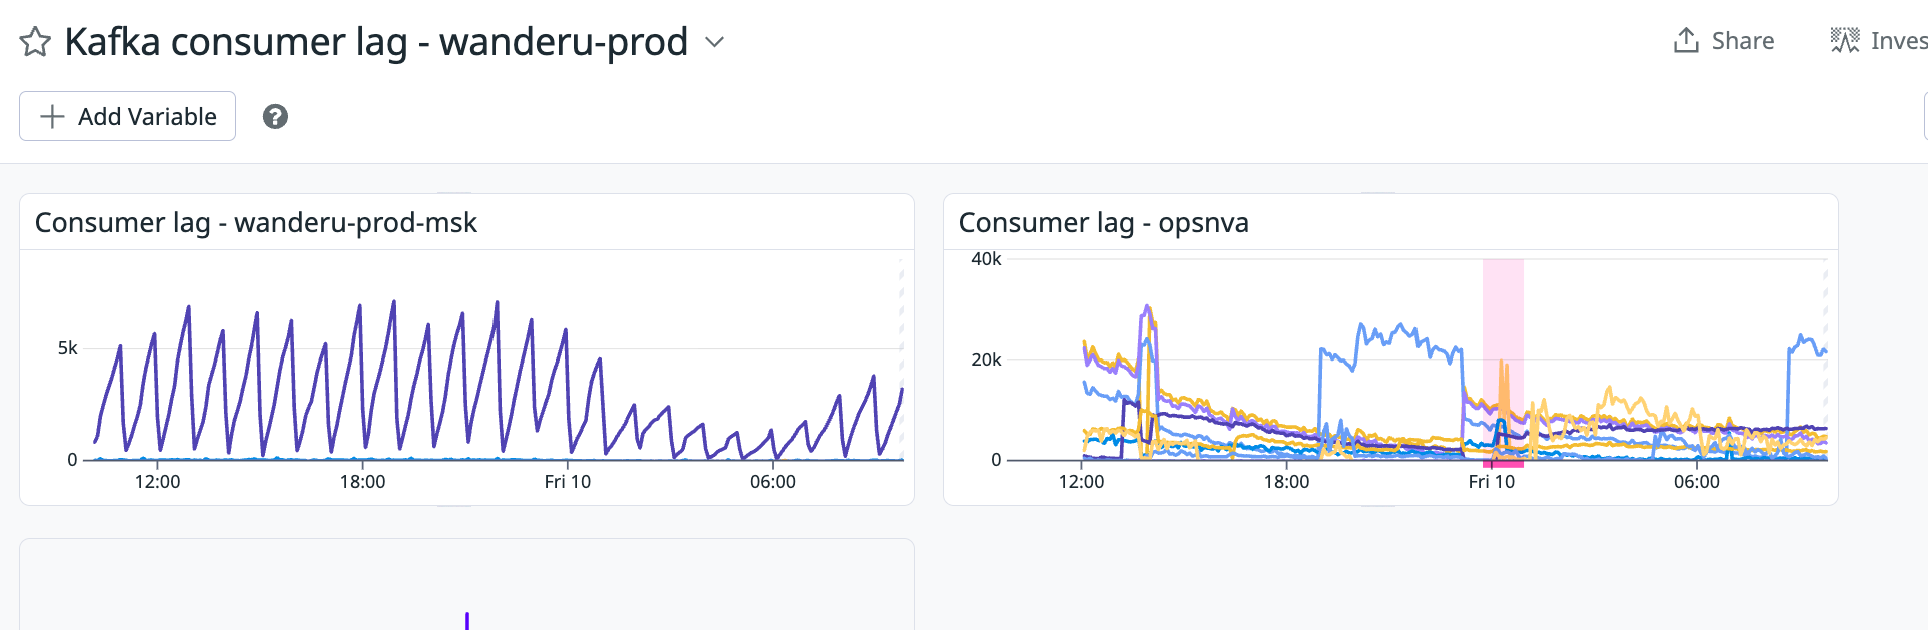
Kafka consumer lag: Burrow out, Datadog in
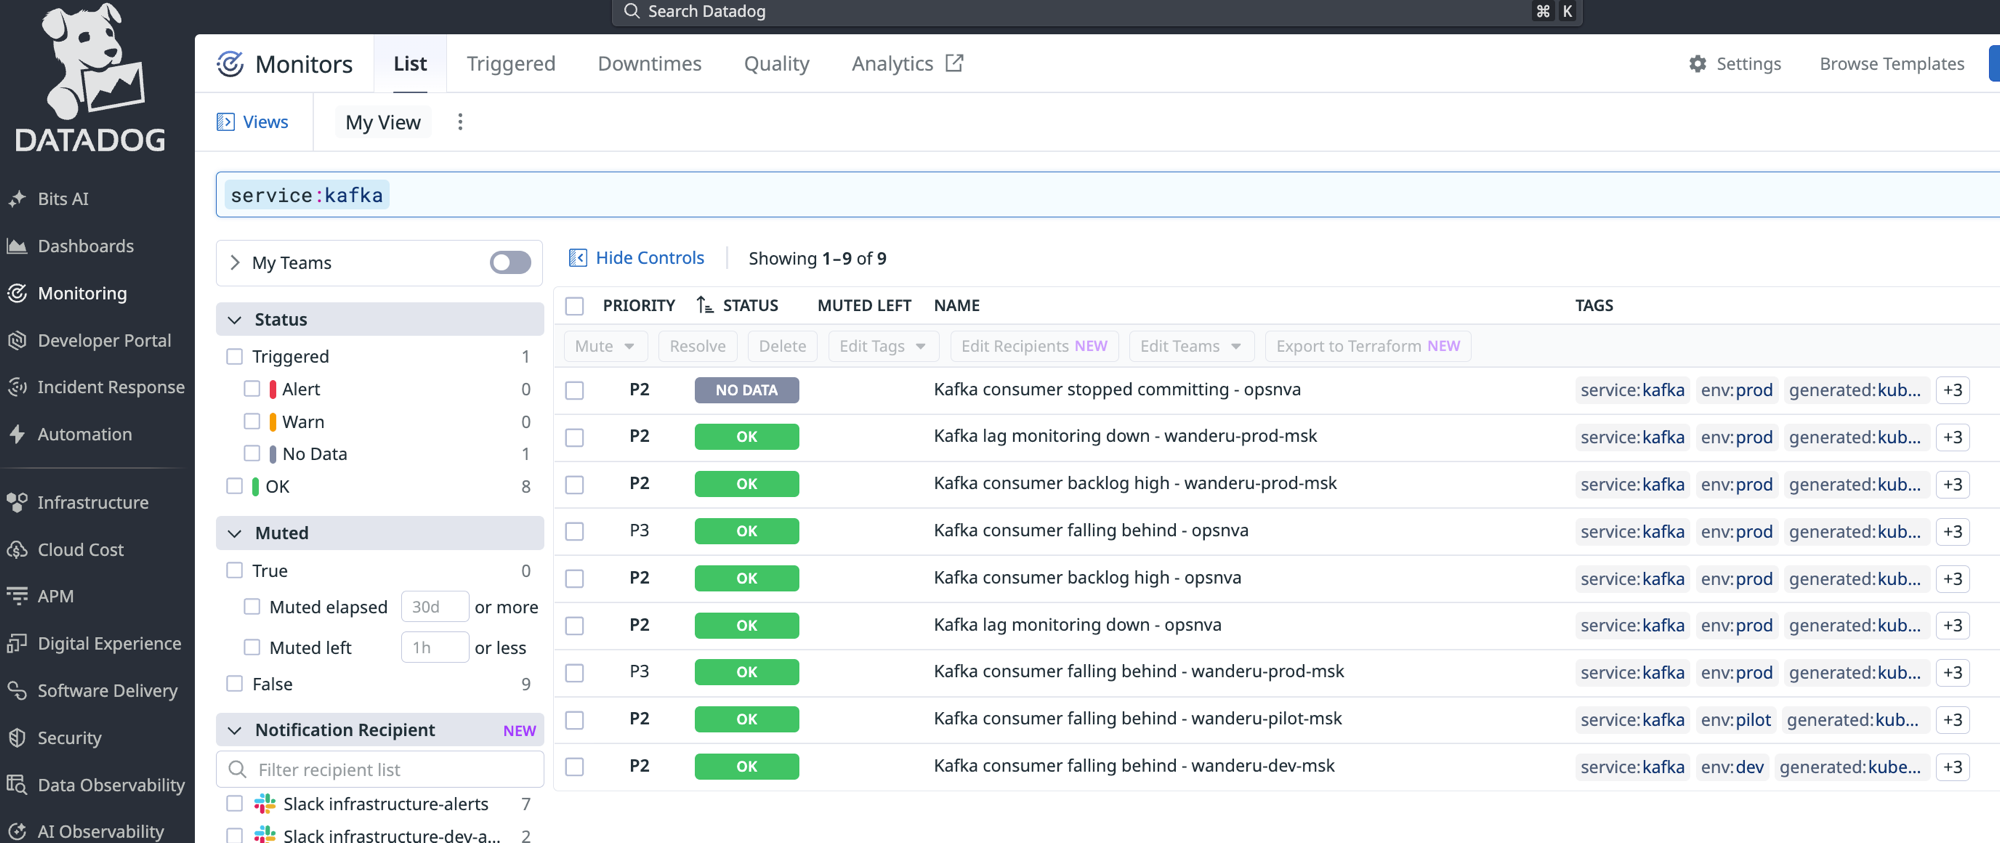
- Burrow replaced by Datadog's kafka_consumer checks on dev, pilot, and prod MSK — plus a custom check for the legacy Kafka 0.10.2 cluster
- Per-cluster monitors: falling behind, backlog high, commits stalled — and a meta-monitor if lag monitoring itself goes down
- Alerts route to Slack — prod to #infrastructure-alerts, the rest to #infrastructure-dev-alerts
Why it matters
Topic lag is how we keep the warehouse current — catching failed pipeline infrastructure before anyone notices missing data. And it makes Burrow retirable.